

Intro: The Internet is “Dead”
There is a burgeoning belief in certain corners of the internet that the internet itself is “dying.” Like any extremely-online theory, this framework began on a message board with a stupid name—in this case, Wizardchan—written by an anonymous internetgoer with an even sillier web handle: Illuminati Pirate.
Mr. Pirate’s post, titled “Dead Internet Theory: Most of the Internet is Fake,” is an anti-government conspiracy theory that conceives of a “Dead Internet” where all major websites are overwhelmed by propagandistic bots in an effort to control the population and reduce human interaction. This was first posed in 2022, months before the launch of ChatGPT.
The following year, generative AI went mainstream, and the Dead Internet concept evolved from a screed against state-sponsored panopticons into an existential anxiety about the rapid growth of AI-generated content. In 2026, the “Dead Internet” is a synthetic projection of humanity, with most of its content generated by LLMs and bots.
Typically, I’m pretty skeptical of any online theory that began on a message board called Wizardchan, so I wanted to investigate claims of the internet’s demise all on my own. How artificial have our digital lives become, and what happens when humanity’s knowledge base is no longer curated by humans?
What Happens When AI Starts Citing Itself?
Long before the Internet (as in 2,450 years ago), there was Plato’s cave. In his book The Republic, Plato hypothesizes a world where humans are held prisoner in a cave and can understand the outside world only through shadows cast on cave walls. One day, a prisoner escapes only to realize that these shadow-like projections offered a distorted representation of authentic human life.
Plato’s cave is almost too tidy an allegory for our digital lives; simply replace the word “cave” with “TikTok” or “Twitter” and the word “shadows” with “fake news” or “AI slop.” Humans are inundated with far too much information, with approximately 4.4 million online articles published each day—basically 4.4 million cave shadows.
As of April 2026, researchers estimate half of this newly published digital content is the product of generative AI, up from 5% in 2022.
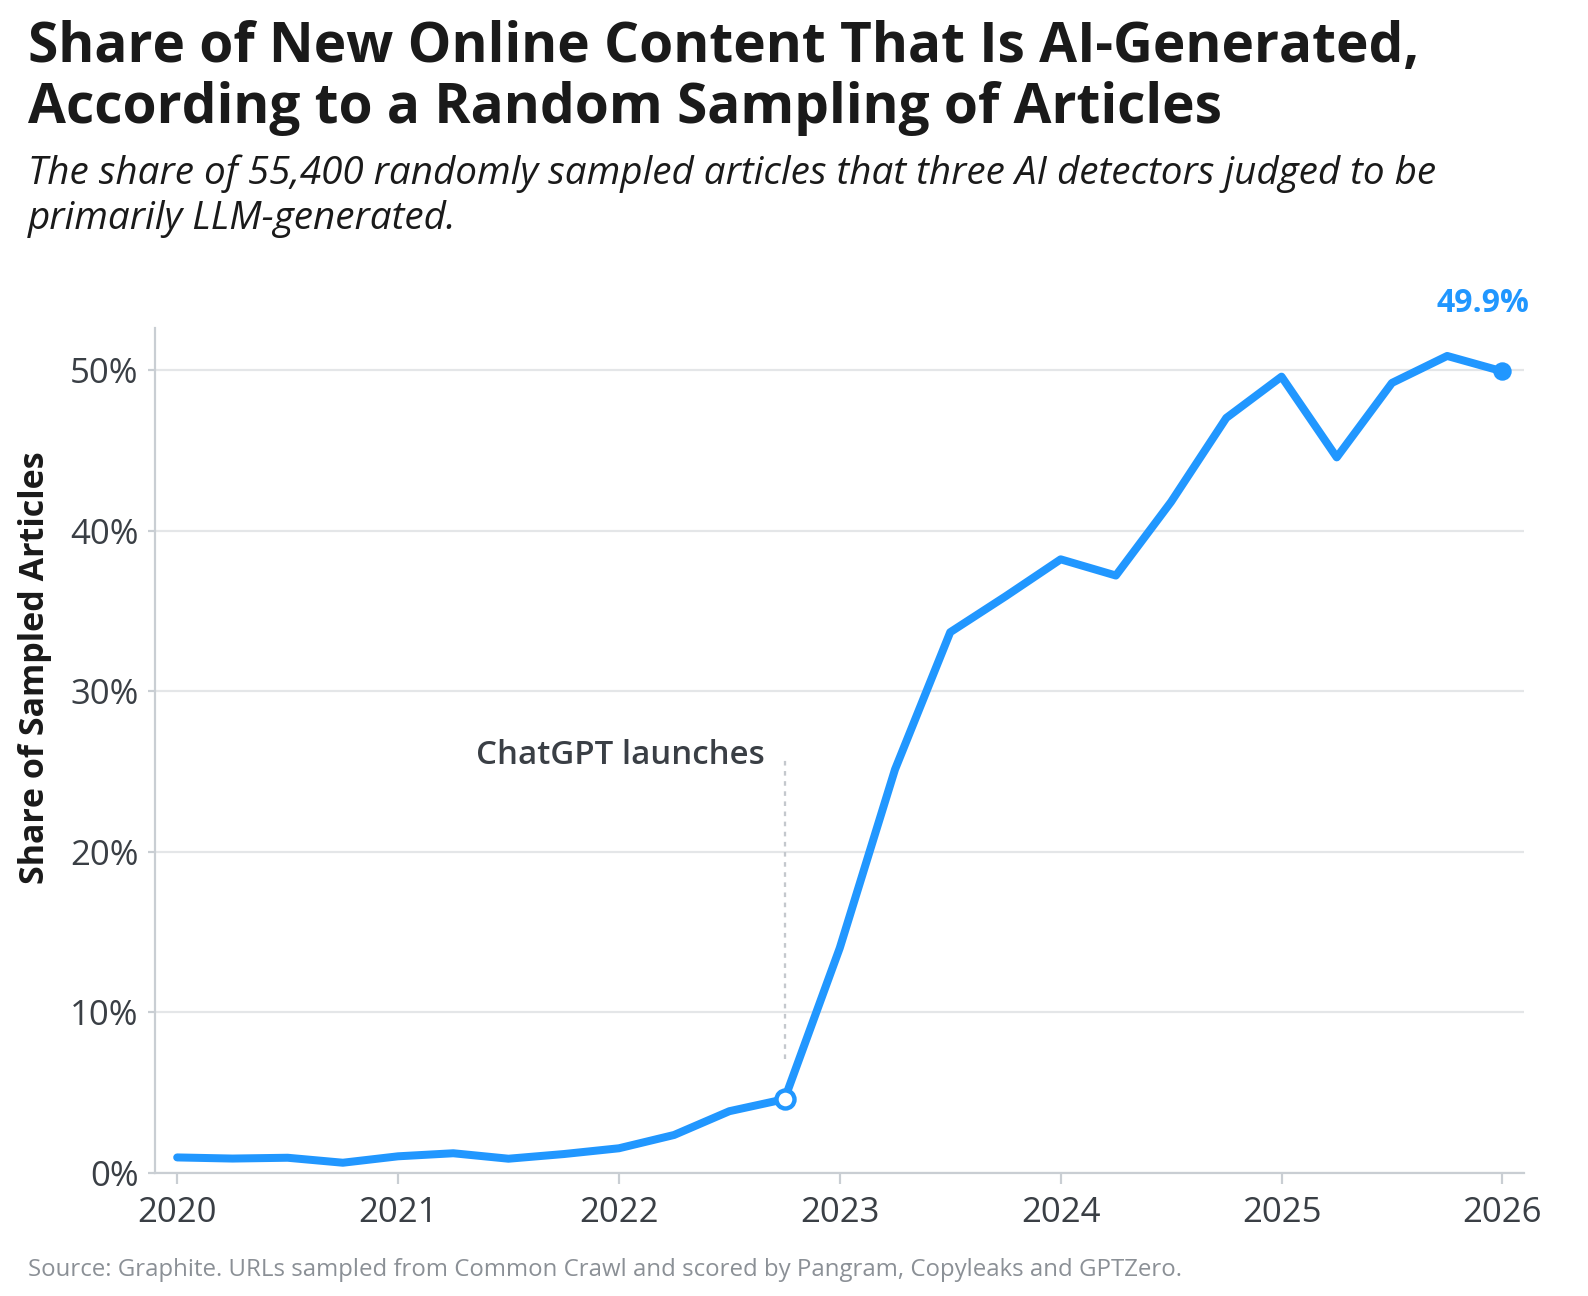
Had you shown this to me three years ago, I probably would have said, “Well, that’s bad, but ChatGPT is mostly scraping Wikipedia, so it’s just regurgitating a source I trust.” That was then. After three years of prolific AI slop production, the situation looks very different.
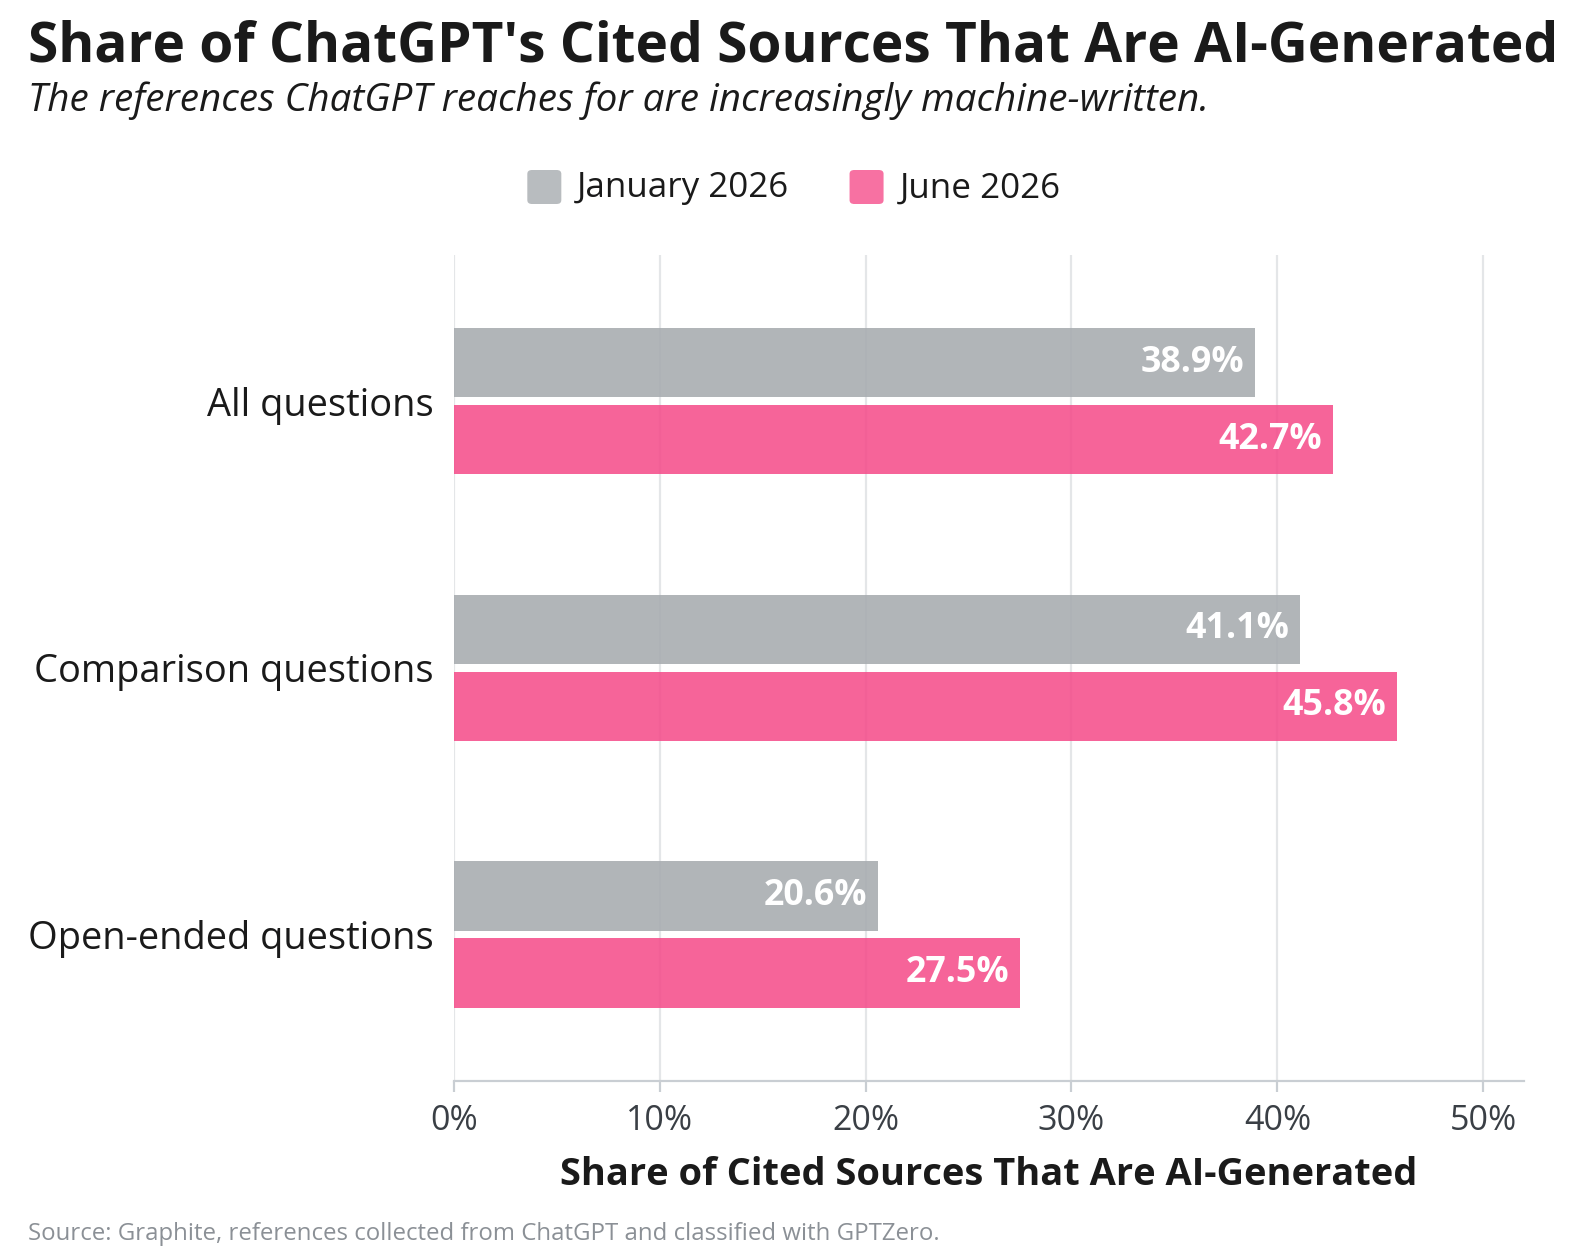
According to a June 2026 study from Graphite, 43% of sources cited by ChatGPT are now LLM-generated—the AI equivalent of a person who loves the sound of their own voice.
Knowledge can now exist in AI-generated silos, synthesized or hallucinated by a chatbot that later regurgitates that hallucination as fact. This raises a rather unsavory brain teaser: If 50% of the internet is now AI-generated, what happens when large language models are trained on their own output? The downstream effect can best be summarized as “garbage in, garbage out,” though the tech industry has dressed the phenomenon up with more technical language: response collapse.
Response collapse stems from two distinct problems, each reinforcing the other.
The first issue is convergence, as models begin generating a narrow range of answers, recycling the same ideas and conclusions in response to similar prompts.
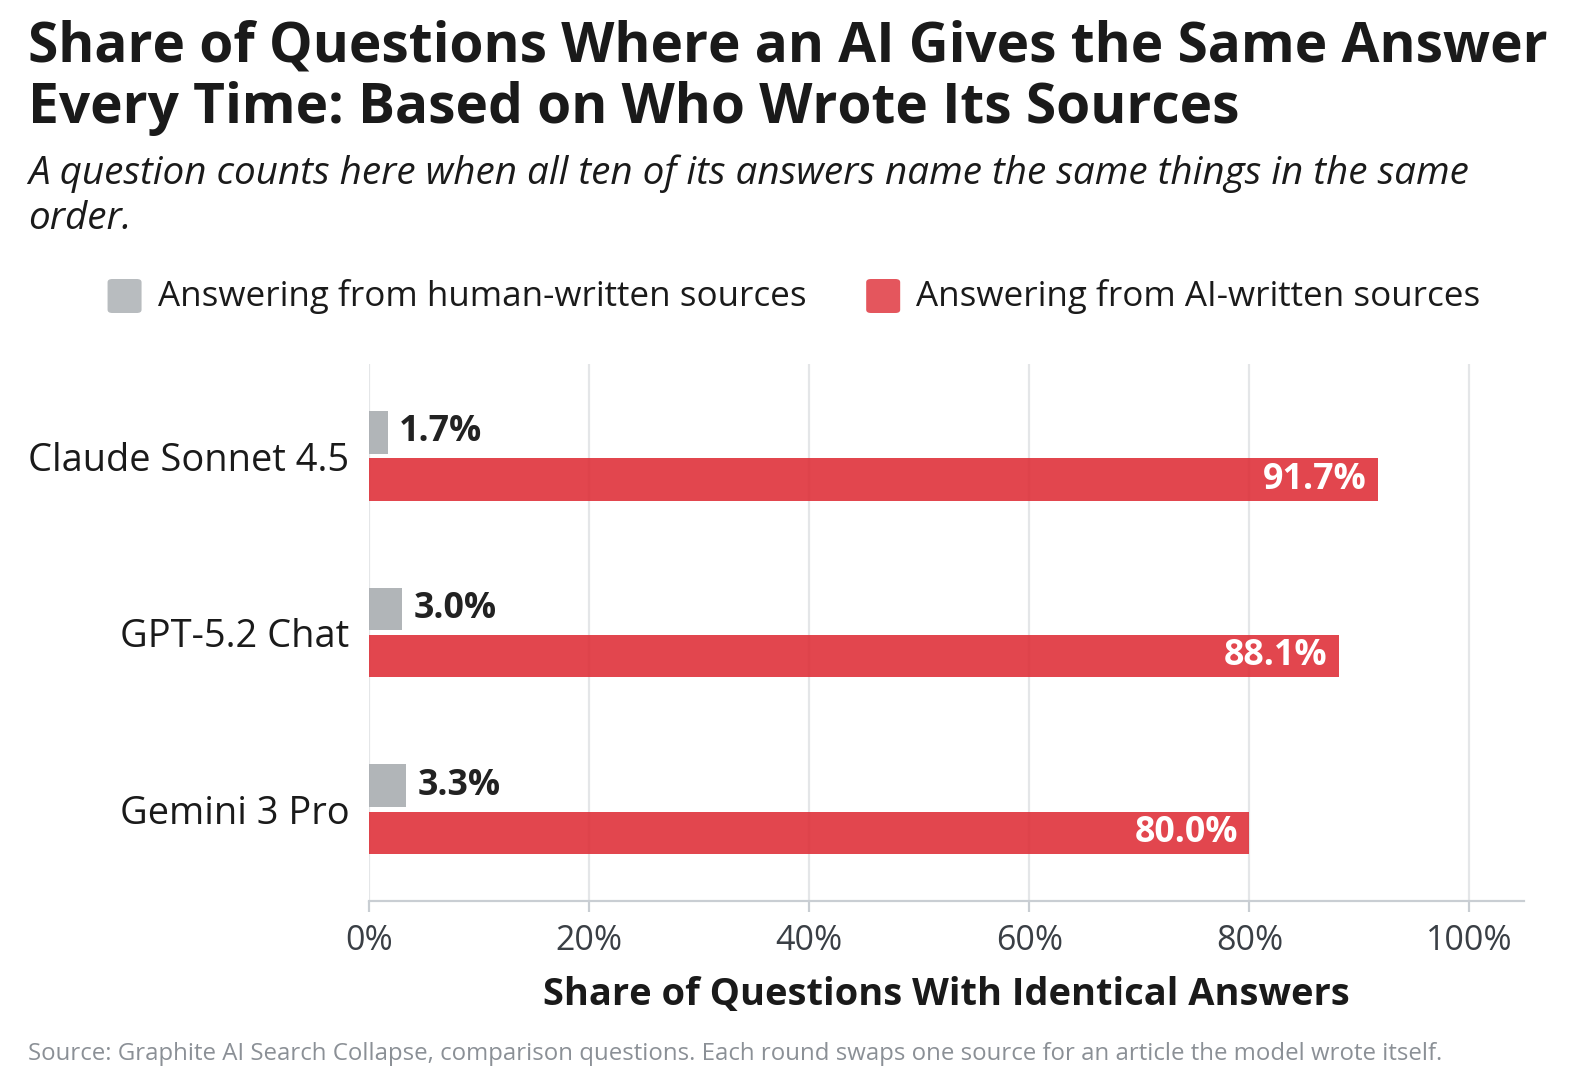
The second problem is degraded model performance for chatbots like Claude and Perplexity, which favor their own output over better human-written answers.
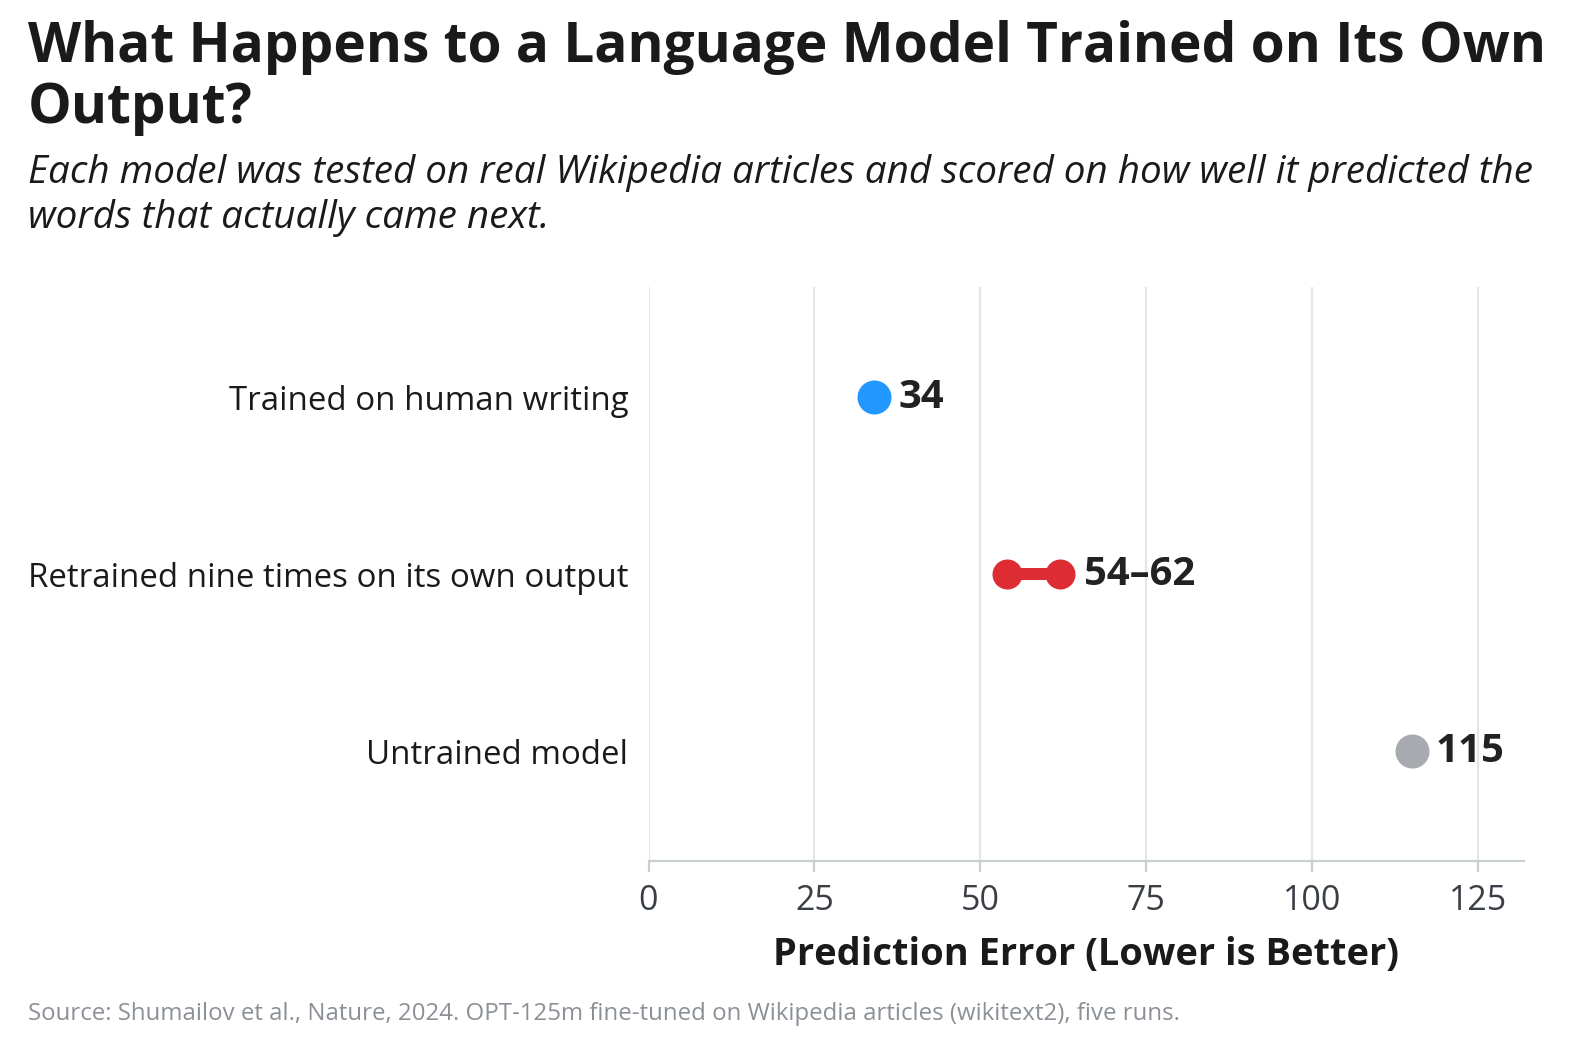
This synthetic drift away from human-curated truth is occurring just as people place more trust in AI-generated summaries and recommendations.
According to a recent study of Google search behavior, 68% of searches now end without a click, as AI-generated blurbs answer a user’s questions before they scroll to the article recommendations below. When an AI summary does appear, that search session is more likely to end there, with the synthesized blurb accepted at face value.
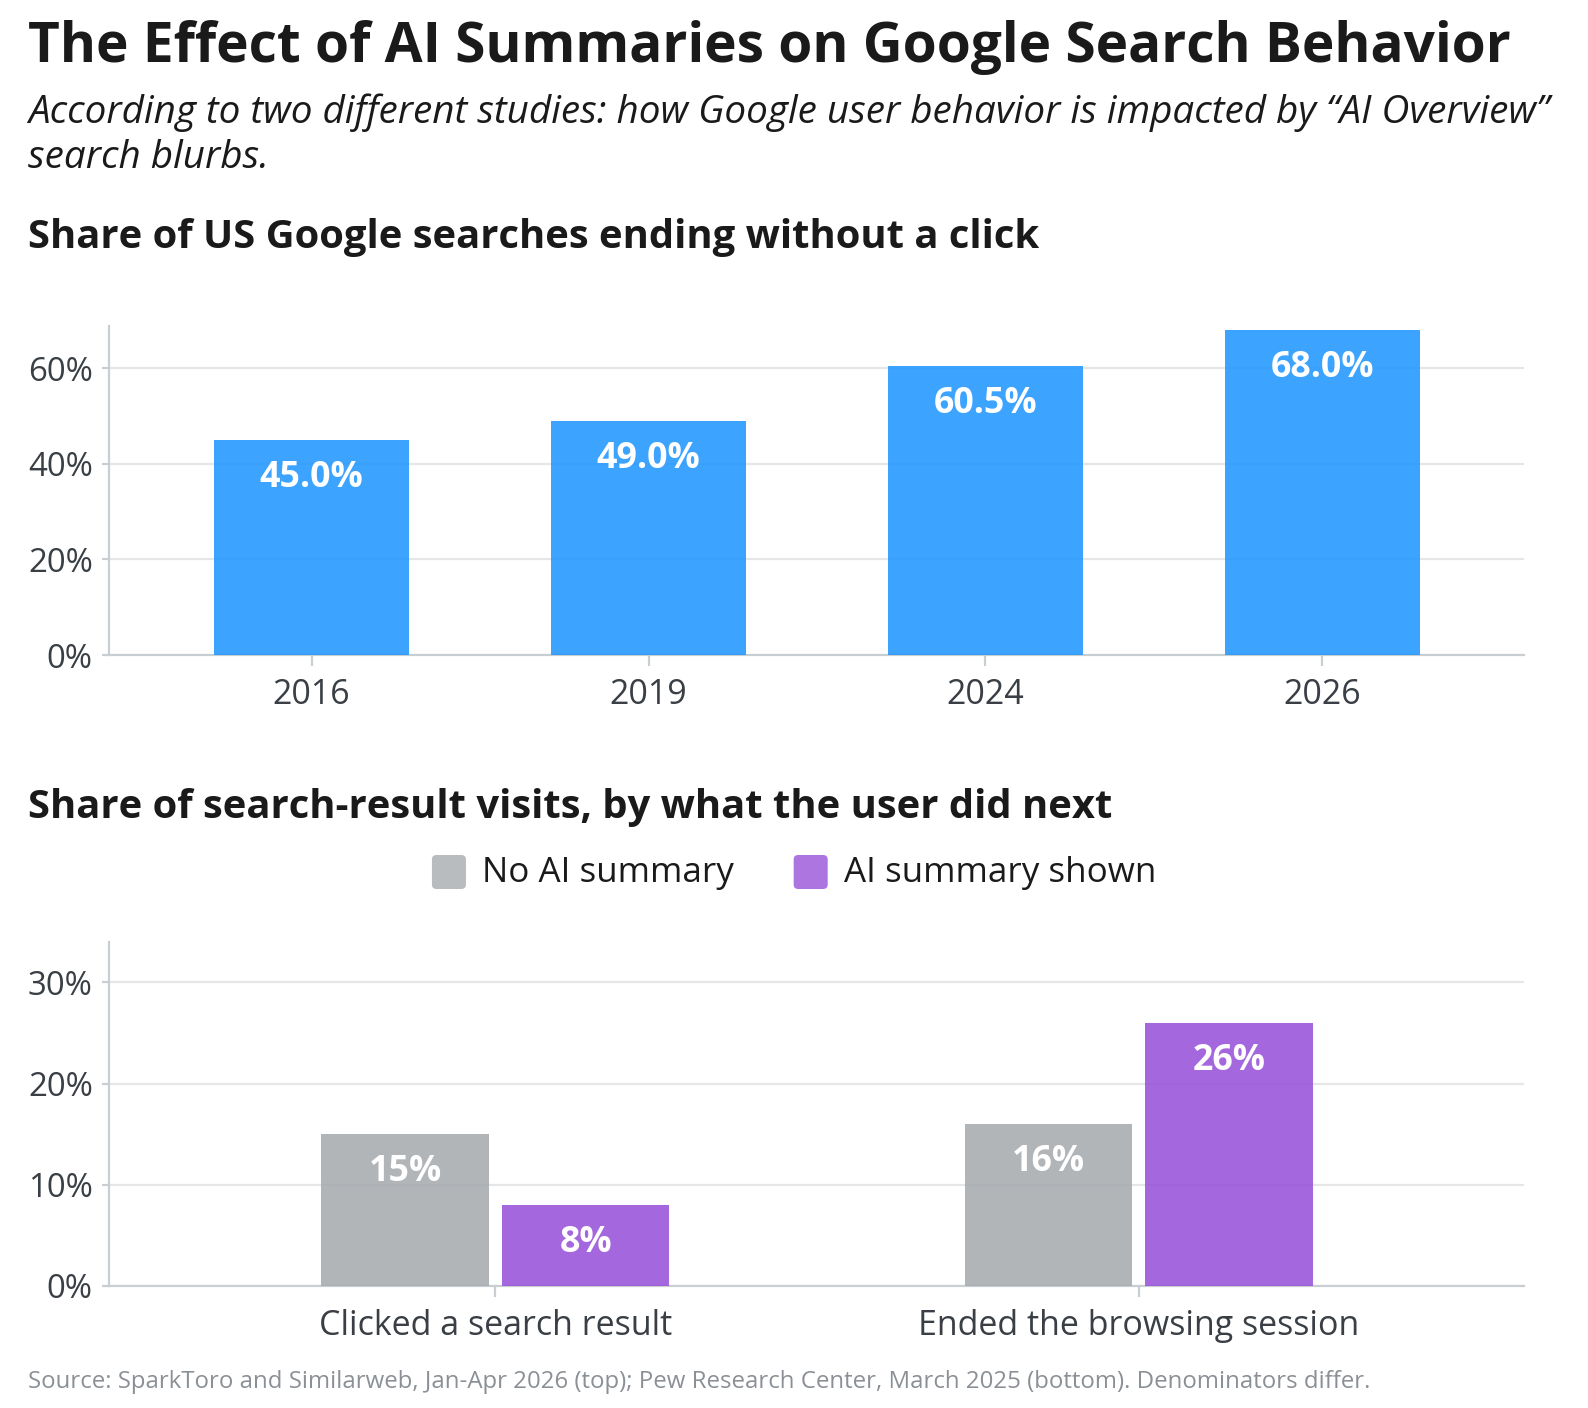
Our shared understanding of capital-T “Truth” was once cultivated by humans; now, that collective knowledge base is being outsourced to AI systems just as people are beginning to trust their outputs almost absent-mindedly.
For now, that may be fine. These chatbots can still trace an answer back to a primary source like Wikipedia. However, several generations from now, ChatGPT may cite an article it produced three years earlier, which cites another AI-generated article from five years earlier, until the chain eventually leads back to something a human once wrote.
The Dead Internet, then, is one where much of what we read, whether a social post or an educational article, is increasingly devoid of humanity: a synthetic projection of something a person wrote years ago, back in the “before times.”
Enjoying the article thus far and want more data-centric pop culture content?
Final Thoughts: LinkedIn, the “Dead-est” Place on the Internet
If you read a high-minded publication like The Atlantic or The New York Times, you’ll find several articles a week about “the end of [insert some liberal principle or societal structure].” Personally, I have read so many of these essays that I’ve developed my own ritual to accompany their consumption:
I read the essay, learning of some imminent disaster that is the first step toward some far-off future hellscape.
I finish the article.
I think to myself, “Well, that’s not going to happen anytime soon. Looks like my children will simply inherit a worse version of planet Earth.”
My dissociation complete, I move on with my day.
While finalizing the research for this piece, my instinct was to retreat into the comfort of this mental model. What fun it is to prophesy future disaster, especially when you’re not held accountable for your predictions. But what if response collapse and synthetic knowledge creep are already here? What if this isn’t some far-off future state? What if the Dead Internet is very much alive on LinkedIn? Yes, that’s right—LinkedIn, as in the worst place on the internet that isn’t 4chan.
According to a recent report from the AI detector Pangram, nearly 45% of LinkedIn posts are the product of a large language model.
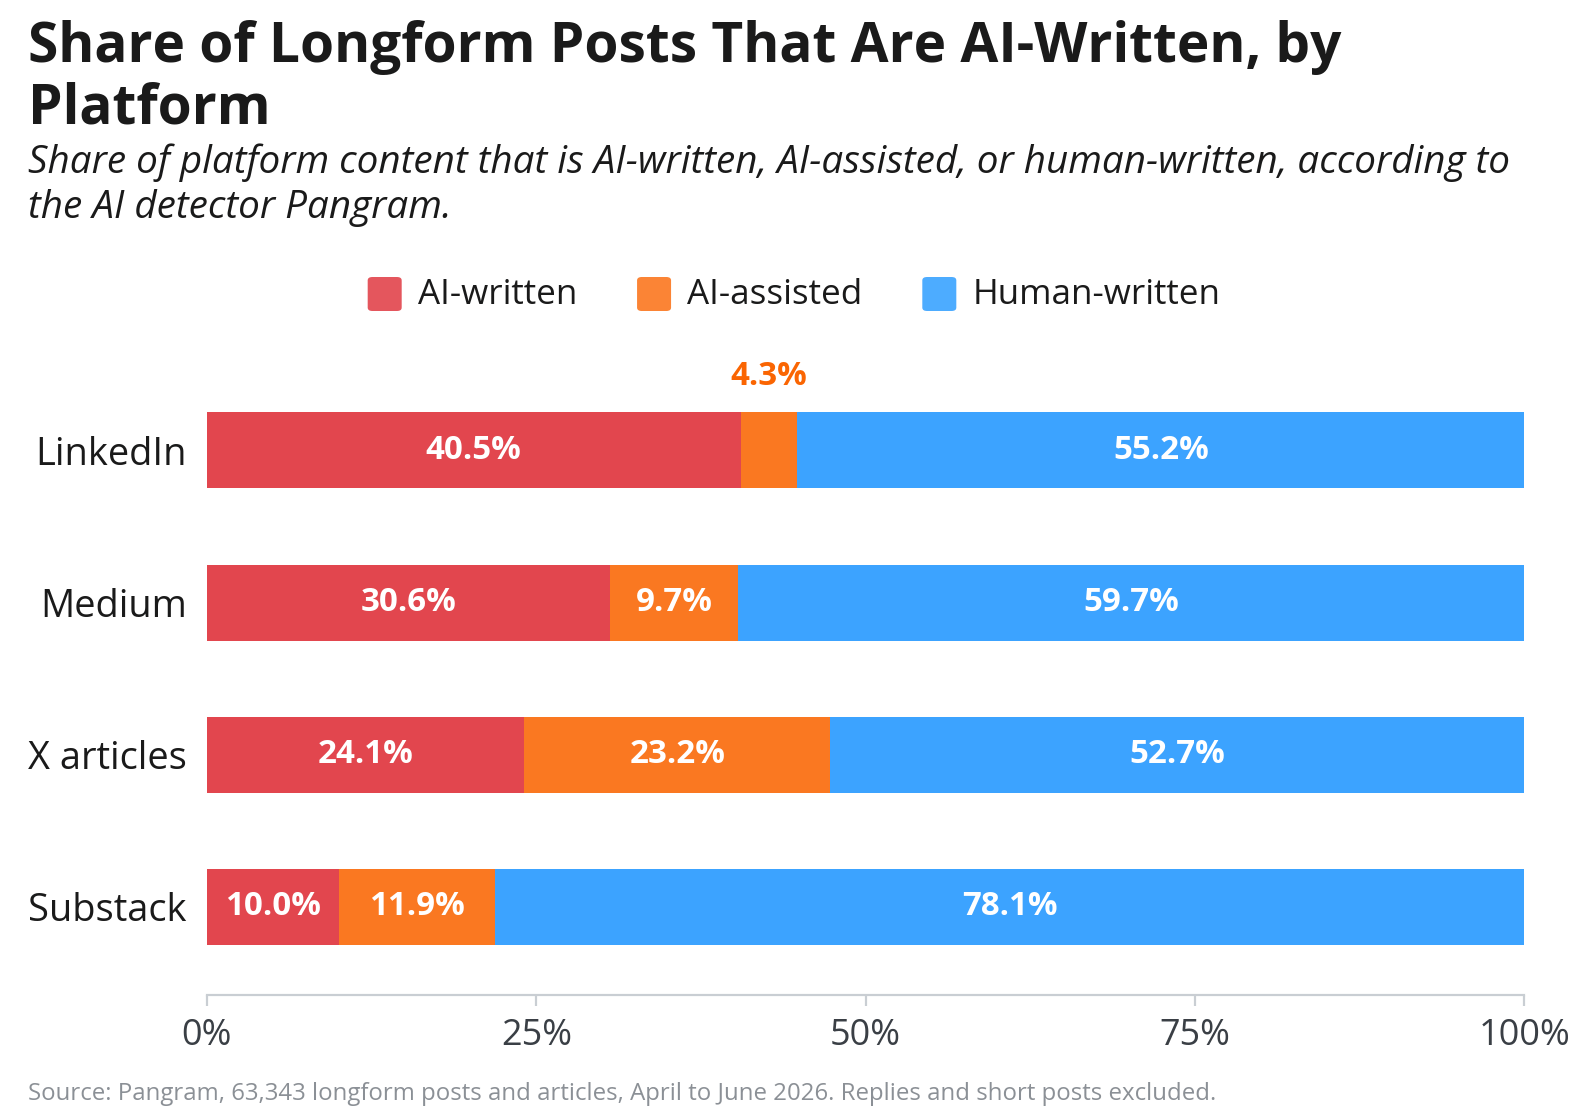
I found this statistic rather surprising; I assumed the number was actually higher. A platform that unironically cultivates a social experience surrounding work will no doubt be the first social network overtaken by robots. LinkedIn is perhaps the foremost example of AI-knowledge drift:
From 2003 to 2023: People who were “good” at LinkedIn honed their approach through trial and error, discerning the type of content other users wanted to see and backsolving the platform’s algorithm.
From 2023 to 2025: Those using ChatGPT and Claude benefited from early adoption. The world rewarded and shared their grindset-mindset content, unaware that these posts were synthetic.
From 2025 onward: Training data for what constitutes a successful post became overwhelmed by AI-generated content. ChatGPT’s outputs began mimicking LinkedIn’s most successful posts—most of which were generated by LLMs.
The year 2036: No human has authored a viral LinkedIn post for some time. The content spread across this social network is a photocopy of a photocopy of a time when humans shared their own thoughts on their favorite productivity hacks and workday rituals. LinkedIn will either be unusable because it lacks humanity, or extremely addictive because ChatGPT and Gemini have converged on the optimal formula for LinkedIn posting.
Sure, LinkedIn may avoid this exact future state, but it’s hard to imagine a world where the site isn’t inundated by generative AI. The real question is whether this fate will be unique to LinkedIn and the sterility of the working world: is this platform an exception—because it’s always been the worst—or is LinkedIn simply further along in humanity’s shift away from organic expression?
A site like LinkedIn may well be on its way to “death,” but death doesn’t mean extinction. More likely, the internet will simply be more banal, composed of synthetic projections of personhood that are, paradoxically, extremely pleasing to humans. Platforms like Wizardchan may very well thrive in the Dead Internet age; what will “die” is the humanity that once produced these posts.
Enjoyed the analysis? Support Stat Significant and unlock the data behind the insights.
Become a paying subscriber to get bonus graphics, interactive dashboards, downloadable datasets, and to support independent journalism.
Paying subscribers get:
Bonus Data Stories: Full access to the Monday Roundup, a weekly bonus edition with extra culture data stories, curated datasets, and recommended reads.
The Public Dataset Directory (Updated Weekly): A curated directory of public datasets from around the web.
Interactive Data Hubs: Interactive dashboards across Streaming TV, Movies, Music, Search Trends, Wikipedia, and more.
*Note: For best results, open this link in a web browser while logged in to your Substack account.
Want to promote your data tool or media publication to Stat Significant’s 26,200 readers? Email daniel@statsignificant.com
Need help with a data problem? Book a free data consultation
Connect with me on LinkedIn if you want to chat about a data project.
Like movies? Follow me on Letterboxd
Excellent article!
One quibble: while Wikipedia is currently an excellent set of human generated summaries, it is by definition NOT a “primary source” and is a “secondary source” instead.
This distinction I think is important past pedantry as a well written Wikipedia article ALSO has links to primary sources as well. This is important as it seems like good training of AI to produce summaries would include them reading complete primary sources and then producing Wikipedia like output rather than just memorizing Wikipedia directly.
I think AI output watermarking and AI detection like pangram can also help a lot for curation of AI training data sets.
However this only removes the first order feedback loop. If AI text starts dominating what humans read on the internet then that will start influencing how humans themselves write, which WILL be picked up in future training. However I don’t see this as necessarily a bad thing. Culture evolves over time even with only humans without AI, so if AI-isms like claudish for example are accepted by large numbers of humans such that LLM compression picks it up in the training set, that’s just the new form of cultural evolution.